Typed Decisions vs LLMs: When You Don't Need a Billion-Parameter Model
Not every AI workflow needs an LLM. For constrained decisions, typed outputs and parallel execution can be faster, cheaper, and easier to trust.
Abhishek Raj
We're using billion-parameter LLMs to make decisions with just three possible answers. Why? That question is the starting point for a better way to design some AI systems: use the smallest, most deterministic approach that can solve the actual problem.
This is not anti-LLM. I use them when the problem is ambiguous and language-heavy. But while building rule-driven workflows, I have repeatedly found that the expensive part is not generating an answer—it is proving that the answer can safely drive the next step. If the choices are known, I want a system that makes invalid choices hard or impossible.
This article expands on my original post about Jev by TypeSafe AI, which focuses on parallel decisions, typed outputs, and low-cost execution. The broader engineering idea matters even if the tools change.
Not Every Decision Needs an LLM
Large language models are powerful when a task needs language understanding, synthesis, ambiguity handling, or open-ended generation. But many product decisions are constrained: approve or reject, choose one of three routes, validate a schema, apply a policy, or classify a known input.
Using a general-purpose LLM for every one of those steps can add latency, cost, and nondeterminism without improving the outcome. Before adding a model call, ask: is this genuinely a language problem, or is it a rules, data, or classification problem with a small answer space?
Typed Outputs Are an Engineering Advantage
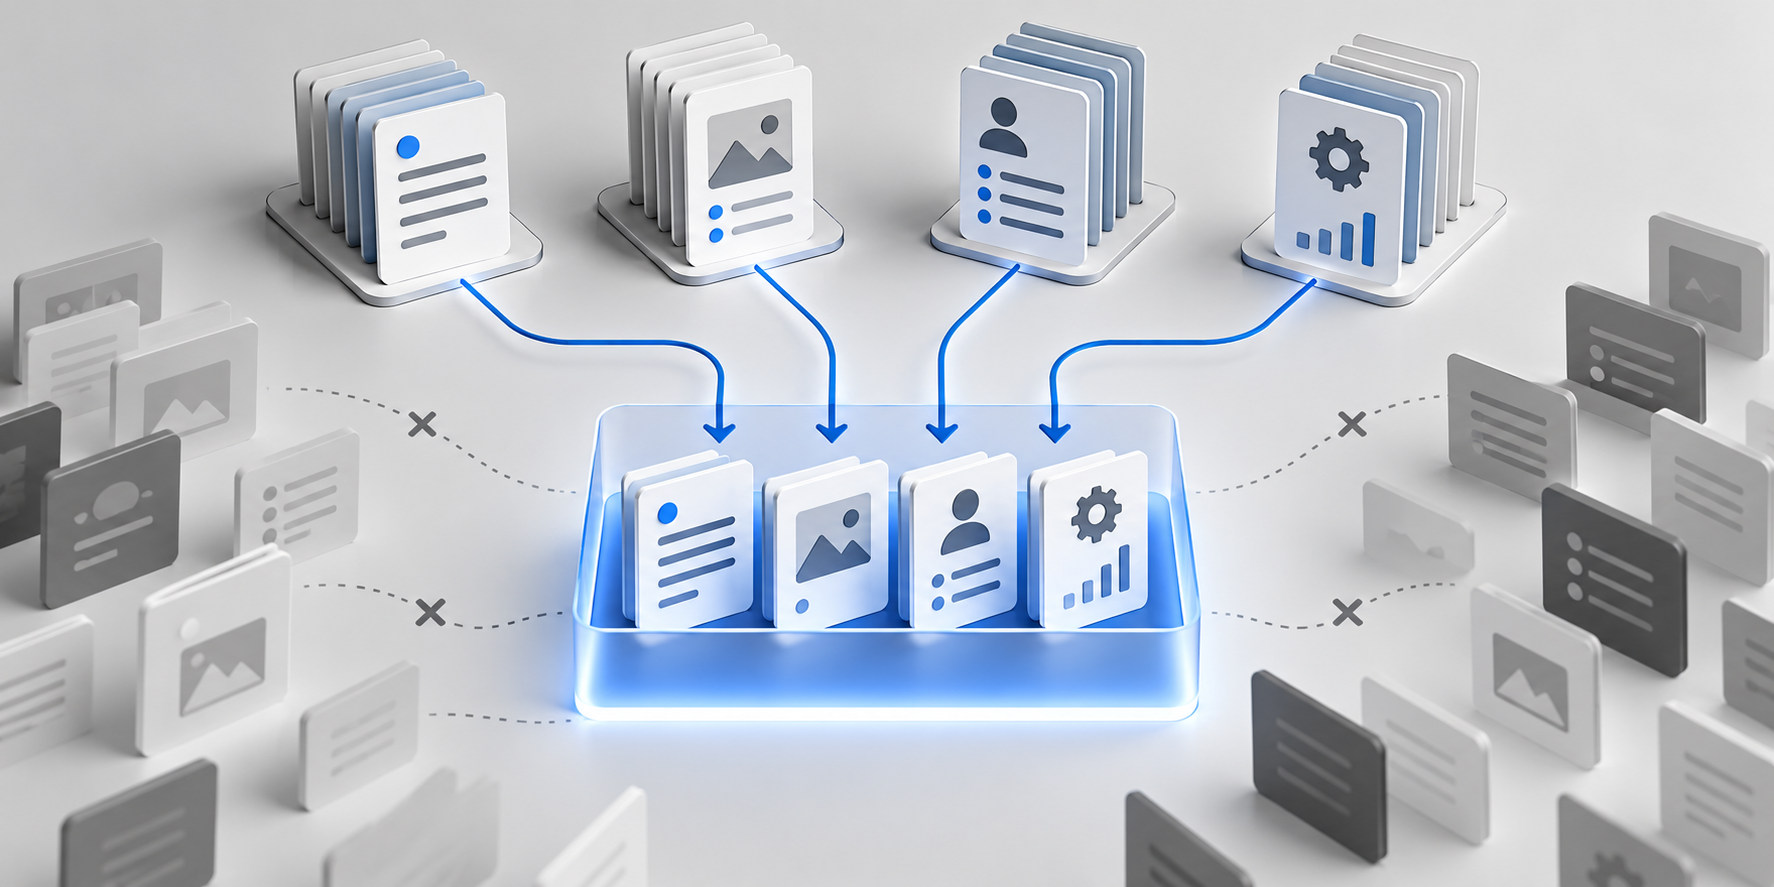
Typed outputs force a system to return data in a known shape. Instead of asking an AI to respond with free-form text and hoping it follows a format, define the allowed fields and values. That makes the result easier to validate, test, store, and pass into the next step of a workflow.
For example, a routing decision might return only a destination, confidence level, and reason code. Application code can reject invalid values before an action is taken. This turns AI output from a paragraph that needs interpretation into an interface that software can safely use.
Parallel Decisions Improve the Critical Path
Some decisions do not depend on one another. A system can check eligibility, detect risk, and validate a payload at the same time, then combine the results. Parallelism reduces end-to-end waiting time when tasks are independent.
The important caveat is independence. Parallel work is not free: it adds coordination, failure handling, and observability requirements. Use it where it shortens the path to a verified result, not simply because an AI workflow can call several workers.
Choose the Smallest Reliable System
The best AI architecture is not the one with the largest model. It is the one that produces a correct, explainable result at an acceptable cost and latency. A practical decision ladder is: use normal application logic for deterministic rules, use constrained models or classifiers for narrow judgments, and use an LLM where language reasoning creates real value.
This approach also makes systems easier to debug. When a typed, bounded decision fails, an engineer can see the inputs, rule or model version, and validation result. That is much harder when every operation is hidden inside an open-ended prompt.
A Useful Design Question
For every LLM call, ask: what is the smallest set of valid answers, what evidence determines the answer, and how will the application verify it? If the answer space is tiny and the evidence is structured, a traditional function or typed decision engine may be the better tool.
AI-native engineering is not about using an LLM everywhere. It is about matching the capability to the job—and saving expensive model reasoning for the problems that truly need it.
The 60-Second Architecture Check
Write down the valid outputs, the evidence needed, and the cost of a wrong answer. If outputs are few and evidence is structured, start with normal code or a typed decision. Reach for an LLM only when language-based judgment changes the result.